
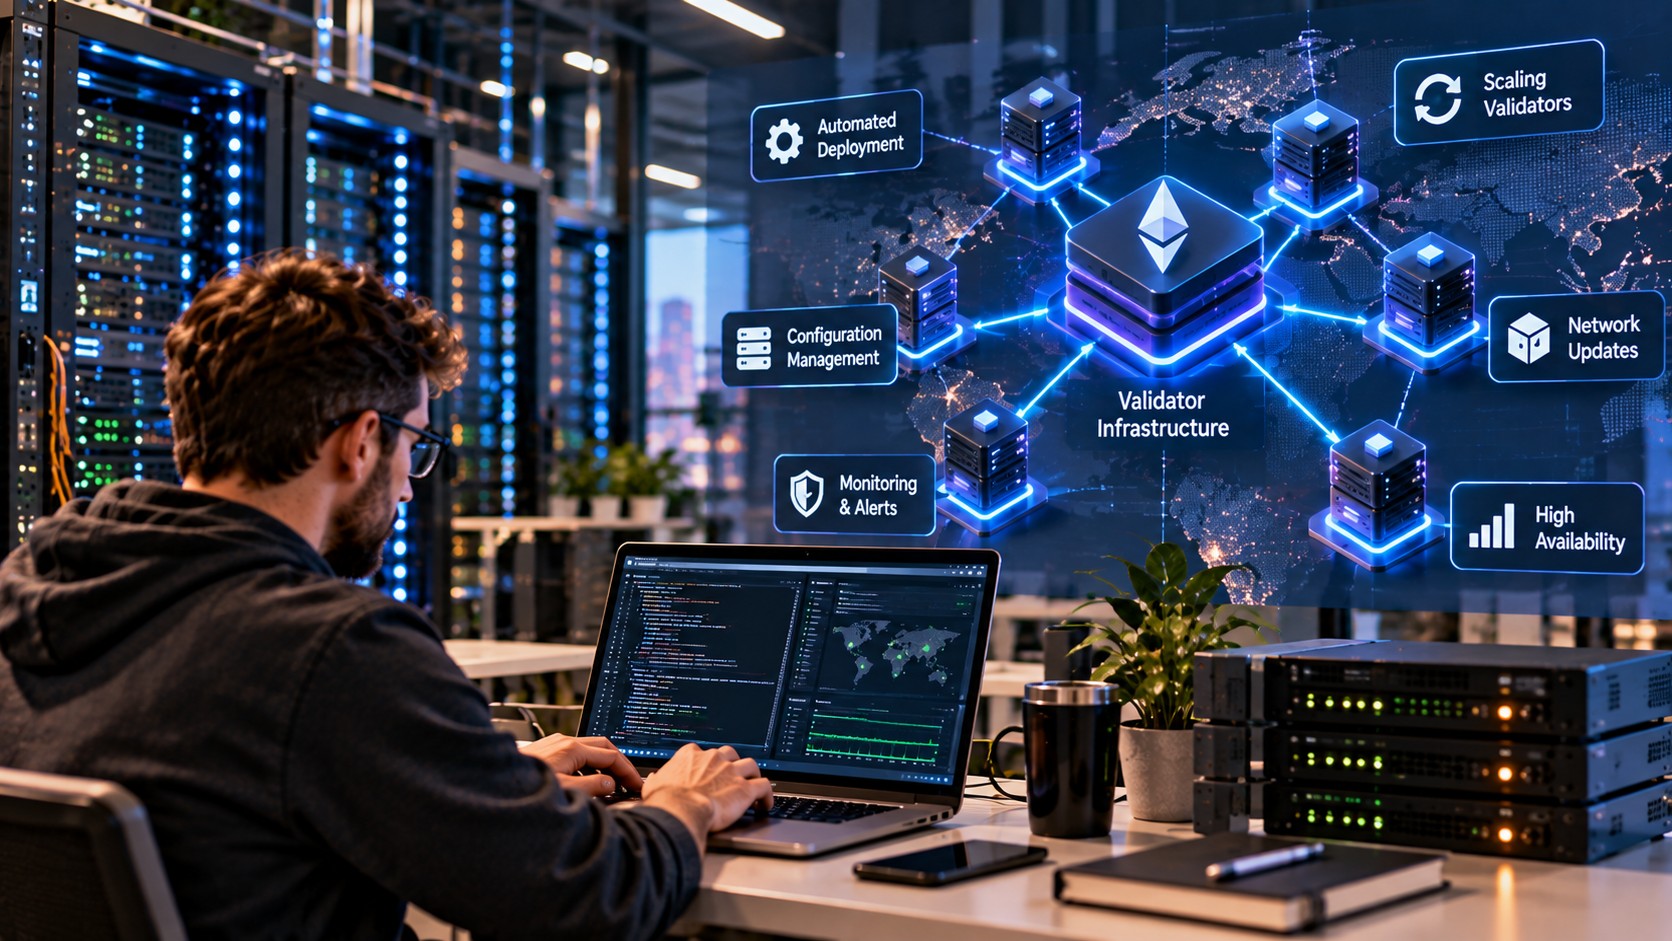
A validator does much more than run a blockchain client. It participates in consensus, processes network data, maintains a continuously changing state, and must remain available when the rest of the network depends on its participation. Even a short interruption can have operational or financial consequences.
For Web3 teams, validator infrastructure therefore needs to be treated as a production system rather than a collection of servers. Automation, observability, controlled maintenance, and reliable recovery procedures can make the difference between an infrastructure operation that reacts to failures and one that anticipates them.
Validator Operations Start with Consistency
Running one validator manually may appear straightforward. Managing multiple nodes across different environments is considerably more demanding.
Client versions, operating-system packages, configuration files, firewall rules, storage settings, credentials, and monitoring agents all need to remain consistent. Small differences between machines can become difficult to diagnose when a validator behaves differently from its peers.
DevOps for Web3 projects introduces repeatable infrastructure practices that reduce this configuration drift. Infrastructure as code can define how validator environments are created and maintained, while automation can apply approved changes across a fleet.
This also makes infrastructure easier to reproduce when a new validator needs to be provisioned.
Protecting the Validator From Infrastructure Failure
Storage Is a Core Dependency
Blockchain clients continuously write and read data. Storage performance can therefore influence synchronization, state access, and overall node responsiveness.
Monitoring should track capacity, latency, I/O behavior, and unusual growth patterns rather than waiting until a disk becomes completely full.
Automated alerts can give engineers time to expand storage, replace a failing device, or move workloads before the validator is affected.
Network Reliability Matters Too
Validators require stable communication with peers and other blockchain services. Packet loss, connectivity interruptions, restrictive firewall rules, or poorly configured networking can degrade participation even when the underlying machine appears healthy.
Redundant network paths, carefully managed firewall policies, and continuous connectivity monitoring can reduce these risks.
Making Validator Updates Less Risky
Blockchain clients evolve continuously. Updates may introduce performance improvements, security fixes, compatibility changes, or new protocol requirements.
Applying every update manually across a validator fleet can create inconsistency. Leaving nodes outdated for too long creates another risk.
A controlled deployment process provides a middle ground.
Test Before Broad Deployment
A new client version can first be evaluated in a non-production environment or on a limited portion of the infrastructure. Engineers can verify synchronization behavior, resource consumption, compatibility, and logs before expanding the rollout.
Automated health checks can then confirm that updated validators are operating normally.
This is one area where DevOps as a Service can be valuable for Web3 organizations that need experienced infrastructure specialists without maintaining a large dedicated operations team.
Observability for Validator Health
Basic uptime monitoring tells only part of the story.
A validator may still respond to network requests while experiencing synchronization delays, peer connectivity problems, excessive resource consumption, or abnormal client behavior.
A useful monitoring system should therefore combine infrastructure and blockchain-specific signals.
What Should Be Monitored?
Depending on the blockchain, relevant indicators may include:
- synchronization status and block height;
- peer count and connectivity;
- CPU, memory, and storage utilization;
- disk latency and available capacity;
- client errors and restart frequency;
- network traffic;
- validator-specific participation metrics.
Combining these signals gives operators enough context to distinguish an ordinary workload increase from a condition that could threaten validator performance.
Automating Recovery Without Removing Control
Failures will eventually happen. A process supervisor can restart an unresponsive client, while orchestration systems can replace failed workloads. However, automated recovery should be designed carefully.
Repeatedly restarting a malfunctioning service without identifying the underlying problem can make an incident harder to diagnose.
Recovery automation works best when paired with clear thresholds, structured logging, health checks, and escalation procedures.
For larger validator fleets, infrastructure automation can also standardize recovery actions and reduce dependence on individual engineers knowing the exact configuration of every machine.
Scaling Validator Operations
Web3 projects may begin with a small number of validators and gradually expand across regions, providers, or infrastructure environments. Growth introduces another operational challenge: maintaining the same reliability standards as the fleet becomes larger.
DevOps for Web3 projects helps turn validator management into a repeatable operational process. Provisioning, configuration, monitoring, updates, backups, and recovery can all follow documented and automated workflows.
This is particularly useful when validators are distributed geographically. Teams can apply consistent policies while still accounting for regional differences in connectivity, capacity, and infrastructure providers.
DevOps as a Service can further extend this capability by providing specialized cloud and automation expertise during expansion, migrations, or major infrastructure changes.
The objective is not to automate every decision. It is to automate repetitive operational work while giving engineers better information and stronger controls over the decisions that affect validator reliability. For Web3 infrastructure, that combination creates a more resilient foundation for continuous network participation.